TRANSLATION · 자동번역
「프론티어의 속도 조절」 성명
Pacing the Frontier
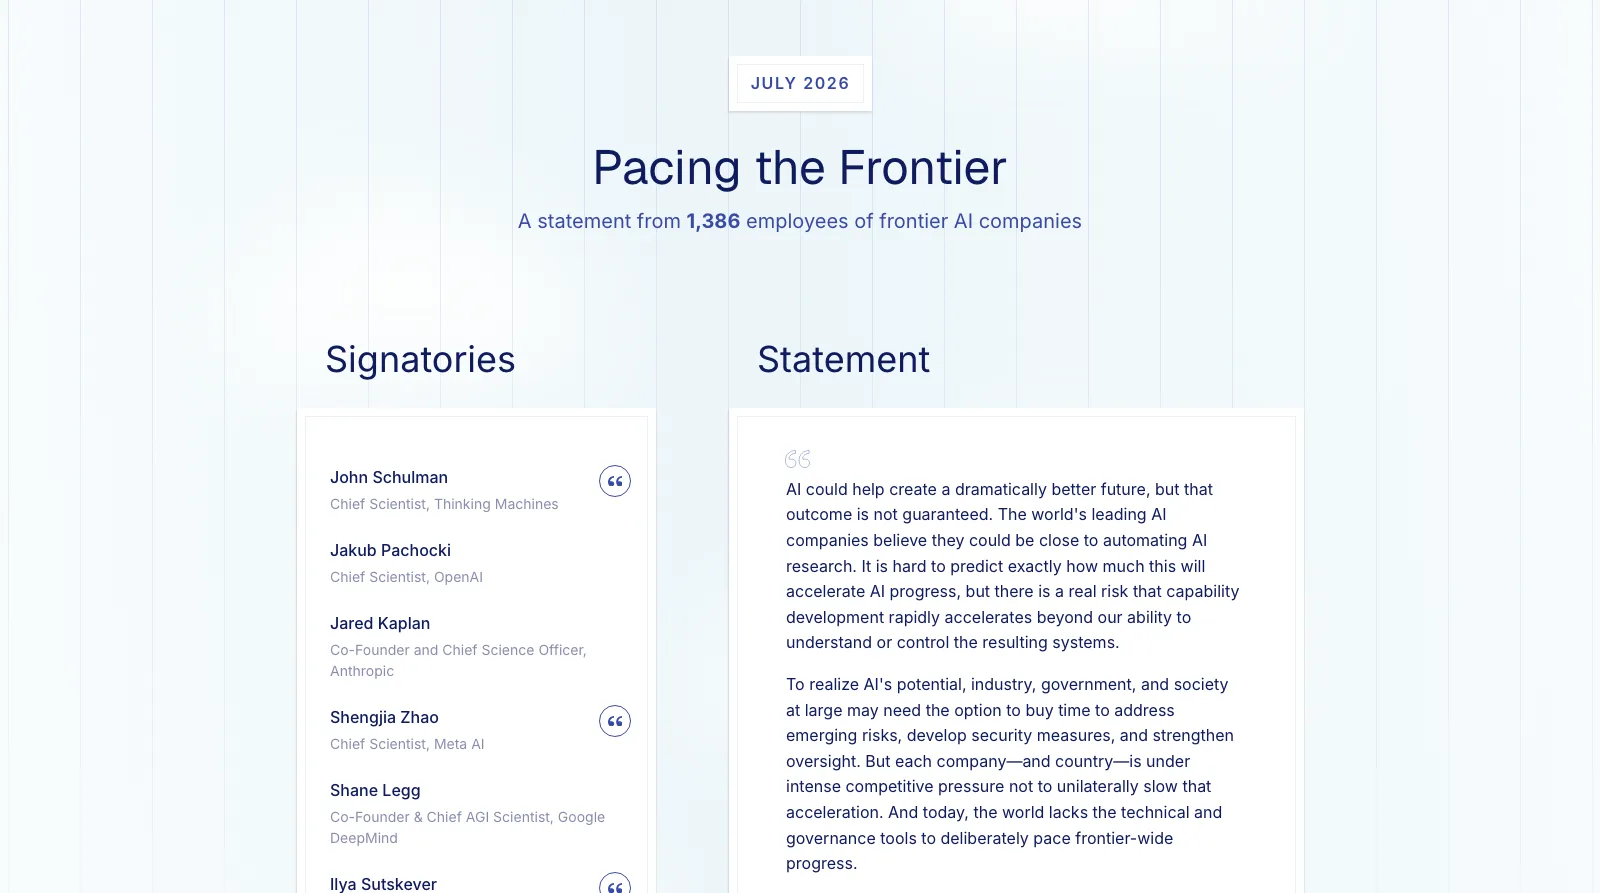
성명서
Statement
AI는 극적으로 더 나은 미래를 만드는 데 기여할 수 있지만, 그러한 결과가 보장된 것은 아니다. 세계 선도 AI 기업들은 자신들이 AI 연구 자동화에 근접했을 수 있다고 본다. 이것이 AI 발전을 정확히 얼마나 가속할지는 예측하기 어렵지만, 역량 개발이 급속히 가속되어 그 결과로 나타나는 시스템을 이해하거나 통제할 수 있는 우리의 능력을 넘어설 실질적 위험이 존재한다.
AI could help create a dramatically better future, but that outcome is not guaranteed. The world's leading AI companies believe they could be close to automating AI research. It is hard to predict exactly how much this will accelerate AI progress, but there is a real risk that capability development rapidly accelerates beyond our ability to understand or control the resulting systems.
AI의 잠재력을 실현하기 위해 산업계, 정부, 그리고 사회 전반은 신흥 위험에 대응하고, 보안 조치를 개발하며, 감독을 강화할 시간을 벌 수 있는 선택지가 필요할 수 있다. 그러나 각 기업과 국가는 그러한 가속을 일방적으로 늦추지 말라는 강한 경쟁 압력을 받고 있다. 그리고 오늘날 세계에는 프론티어 전반의 진전 속도를 의도적으로 조절할 기술적·거버넌스적 도구가 부재하다.
To realize AI's potential, industry, government, and society at large may need the option to buy time to address emerging risks, develop security measures, and strengthen oversight. But each company—and country—is under intense competitive pressure not to unilaterally slow that acceleration. And today, the world lacks the technical and governance tools to deliberately pace frontier-wide progress.
프론티어 모델 공개를 모니터링하기 위해 이미 진행 중인 작업을 기반으로 하여:
Building on work already underway to monitor frontier model releases:
우리는 미국 정부가 자동화된 AI 개발 프론티어의 속도를 의도적으로 조절하는 데 필요한 기술적·거버넌스적 도구를 개발하기 위한 국제적 노력을 지원할 것을 요청한다.
We request that the U.S. government support an international effort to develop the technical and governance tools needed to deliberately pace the frontier of automated AI development.
서명자
Signatories
John Schulman — 수석 과학자, Thinking Machines
John Schulman — Chief Scientist, Thinking Machines
Jakub Pachocki — 수석 과학자, OpenAI
Jakub Pachocki — Chief Scientist, OpenAI
Jared Kaplan — 공동창업자 겸 최고과학책임자, Anthropic
Jared Kaplan — Co-Founder and Chief Science Officer, Anthropic
Shengjia Zhao — 수석 과학자, Meta AI
Shengjia Zhao — Chief Scientist, Meta AI
Shane Legg — 공동창업자 겸 인공일반지능(AGI) 수석 과학자, Google DeepMind
Shane Legg — Co-Founder & Chief AGI Scientist, Google DeepMind
Ilya Sutskever — CEO, Safe Superintelligence Inc.
Ilya Sutskever — CEO, Safe Superintelligence Inc.
Mark Chen — 최고연구책임자, OpenAI
Mark Chen — Chief Research Officer, OpenAI
Jasjeet Sekhon — 최고전략책임자, Google DeepMind
Jasjeet Sekhon — Chief Strategy Officer, Google DeepMind
Dario Amodei — CEO, Anthropic
Dario Amodei — CEO, Anthropic
Jack Clark — 공동창업자 겸 공익 책임자, Anthropic
Jack Clark — Co-Founder and Head of Public Benefit, Anthropic
Anca Dragan — AI 안전 및 정렬 부사장, Google
Anca Dragan — VP, AI Safety & Alignment, Google
Wojciech Zaremba — AI 회복력 책임자, OpenAI Foundation
Wojciech Zaremba — Head of AI Resilience, OpenAI Foundation
Dawn Song — AI 연구 부사장, Meta
Dawn Song — VP, AI Research, Meta
Chris Olah — 공동창업자 겸 해석가능성 연구 책임자, Anthropic
Chris Olah — Co-Founder & Interpretability Research Lead, Anthropic
Laura Weidinger — 스태프 연구 과학자, Google
Laura Weidinger — Staff Research Scientist, Google
Benjamin Mann — 공동창업자, Anthropic
Benjamin Mann — Co-Founder, Anthropic
Stephanie Chan — 스태프 연구 과학자, Google
Stephanie Chan — Staff Research Scientist, Google
Julian Schrittwieser — Anthropic
Julian Schrittwieser — Anthropic
Summer Yue — 정렬 및 위험 디렉터, Meta
Summer Yue — Director of Alignment and Risk, Meta
Jan Leike — Anthropic
Jan Leike — Anthropic
개인 의견
Personal comments
Leo Gao
Leo Gao
기술 스태프, OpenAI
Member of Technical Staff, OpenAI
세계는 지능 폭발을 향한 치명적인 경쟁에 갇혀 있다. 지능 폭발이란 더 나은 AI를 만드는 AI의 능력이 마치 통제 불능의 핵 연쇄 반응처럼 임계점에 도달하는 것을 말한다. 속도를 늦추면 이를 잘 풀어 나가는 데 꼭 필요한 시간을 벌 수 있겠지만, 어떤 개별 행위자도 일방적으로 멈추려 하지 않는다. 살아남기 위해 우리는 공조하여 경쟁의 속도를 늦춰야 한다.
The world is locked in a deadly race towards an intelligence explosion, where AI’s ability to create better AIs reaches a critical point, just like a runaway nuclear chain reaction. Going slower would give us much-needed time to make it go well, but no individual actor is willing to stop unilaterally. To survive, we must coordinate to slow down the race.
Matthew Rahtz
Matthew Rahtz
스태프 연구 엔지니어, Google
Staff Research Engineer, Google
AI 역량 평가 업무를 3년간 해 왔음에도 최근의 발전 속도는 충격적이었다. 인공일반지능(AGI)으로 인한 파국적 피해를 피하려면 지금보다 훨씬, 훨씬 더 나은 공조가 필요하다.
Even after 3 years working on AI capability evaluations, the recent pace of progress has been a shock. To avoid catastrophic harms from AGI, we need much, much better coordination.
Christian Ryan
Christian Ryan
기술 스태프, Anthropic
Member of Technical Staff, Anthropic
외국 국적자로서 나는 미국이 지원하는 노력이 자유 세계의 자유뿐 아니라 모든 이의 번영에 있어서도 존립이 걸린 문제라고 본다.
As a foreign national, I see a US-supported effort as existential, not only for the liberties of the free world but for the prosperity of all.
Will Yager
Will Yager
Anthropic
Anthropic
원자 분열과 마찬가지로 AI는 막대한 혜택과 막대한 위험을 모두 품고 있다. 세계는 이를 제대로 해내기 위해 시간을 들여야 한다.
Like splitting the atom, AI holds the potential for both immense benefit and immense risk. The world should take the time to do this right.
Micah Carroll
Micah Carroll
오정렬 대비, OpenAI
Misalignment Preparedness, OpenAI
현재 속도라면 2주에 한 번꼴로 모델 오용과 오정렬의 결과를 크게 증폭시키는 새로운 모델이 등장할 것이다. 나는 이러한 위험을 완화하려는 노력이 개발 속도를 따라가지 못할 수 있으며, 국제적 경쟁 압력 속에서 오류 허용 범위가 점점 더 좁아질 것을 우려한다. 가까운 미래에 우리는 국제적으로 조율된 감속, 또는 AI 개발의 무기한 금지를 시급히 시행하기를 원하게 될 수 있다. 그러한 조치를 촉박한 시점에 취할 수 있도록 신뢰와 인프라를 구축하려는 시도는 그저 신중한 대비일 뿐이다. 적어도 이런 선택지를 확보하려는 시도조차 하지 않을 이유가 어디 있겠는가? 나는 AI 개발을 둘러싼 국제적 바닥으로의 경쟁에서는 어느 국가도 승리하지 못하고 우리 모두가 함께 패배할 가능성이 높다고 우려한다.
At the current pace, every couple of weeks there will be new models which significantly increase the consequences of model misuse and misalignment. I worry that efforts to mitigate these risks may fail to keep up with the pace of development, and that margins for error will become increasingly small under international competitive pressures. In the near future, we may urgently want to enact an internationally coordinated slowdown, or an indefinite ban on AI development. Attempting to build the trust and infrastructure for taking such actions on short notice seems simply prudent – why would we not at least try to have this option? I fear that in an international race to the bottom of AI development, it is likely that no nation will win, and we will all lose together.
Shengjia Zhao
Shengjia Zhao
수석 과학자, Meta AI
Chief Scientist, Meta AI
AI는 우리 사회가 감당할 준비가 되지 않았을 수도 있는 속도로 발전하고 있다. 프론티어 랩들은 거의 모든 지능 지표에서 최고의 인간조차 능가할 수 있는 AI에 매우 근접해 있다. 이는 전례 없는 사회적·안전 위험으로 이어질 것이다. 긍정적인 미래를 보장하기 위해 우리는 책임감과 신중함에 기반하여 AI를 개발해야 한다.
AI is progressing at a rate that our society might not be ready for. Frontier labs are very close to AI that can exceed even the best people on almost every metric of intelligence. This will lead to unprecedented social and safety risks. To ensure a positive future we need to develop AI in a way that is driven by responsibility and thoughtfulness.
John Schulman
John Schulman
수석 과학자, Thinking Machines
Chief Scientist, Thinking Machines
자동화된 AI 연구가 발전을 가속함에 따라 공조 메커니즘이 필요할 수 있다는 점에 대한 공유 지식(common knowledge)을 확립하는 데 이 성명서가 도움이 되기에 서명했다. 또한 나는 미국 정부가 관여하기 전이라도 랩들이 자발적으로 이러한 메커니즘을 설계하기 시작하기를 바란다.
Signed because this statement helps establish common knowledge about the possible need for coordination mechanisms as automated AI research accelerates progress. I'd also like to see labs start designing these mechanisms voluntarily, even before the USG gets involved.
Shantanu Jain
Shantanu Jain
기술 스태프, OpenAI
Member of Technical Staff, OpenAI
4년 사이에 우리는 사람들이 언어를 이해하는 AI를 처음 경험하던 단계에서, 초인적인 소프트웨어 엔지니어링 성과를 내고, 프론티어 수학에서 돌파구를 마련하며, 과학 연구를 가속하는 AI의 단계에 이르렀다. 발전은 둔화될 기미를 보이지 않으며, 미래가 한꺼번에 도래하지 않는 것이 인류에게 최선의 이익이라 할지라도 기본적으로는 개별 기업과 국가가 가속 페달을 끝까지 밟는 것이 각자의 이익에 부합한다. 사회는 인간 지능을 규율하고 감독하기 위한 법, 제도, 기술을 개발하는 데 기억할 수 없을 만큼 오랜 시간을 들여 왔다. 인공지능에 대해서도 같은 일을 하는 데 조금이라도 시간을 쓸 수 있는 선택지를 갖는다면 좋을 것이다.
In the span of four years, we have gone from people having their first experience of an Al that could understand language, to Al that is performing superhuman feats of software engineering, making frontier math breakthroughs, and accelerating scientific research. Progress has shown no signs of slowing down and by default it is in the interest of individual corporations and countries to push the accelerator all the way down, even if it is in humanity's best interest for the future to not arrive all at once. Society has spent longer than we can remember developing the laws, institutions and technology to govern and oversee human intelligence; it would be good to have the option to spend any time at all doing the same for artificial intelligence.
Edward Hughes
Edward Hughes
수석 과학자, Inherent
Chief Scientist, Inherent
Melvin Kranzberg가 썼듯이, 기술은 좋지도 나쁘지도 않으며, 그렇다고 중립적이지도 않다. 사회적 혜택을 달성하는 것은 많은 인간이 첨단 AI 시스템을 협력하여 사용하는 상호의존적인 방식을 이해하는 데 달려 있으며, 그러한 이해를 얻는 데에는 시간이 걸린다. 자동화된 AI 연구를 향한 진전의 속도를 조절하면 사회적 규모의 변화에 대한 이해를 구축할 시간을 확보할 수 있으며, 이를 통해 자기 개선형 AI뿐 아니라 협력적 AI도 얻을 수 있다.
As Melvin Kranzberg wrote, technology is neither good nor bad; nor is it neutral. Achieving societal benefit depends on understanding the interdependent ways in which many humans use advanced AI systems in concert, understanding that takes time to acquire. Pacing progress towards automated AI research allows us the time to build understanding of societal-scale changes, yielding not only an self-improving AI but also a cooperative AI.
Dawn Song
Dawn Song
AI 연구 부사장, Meta
VP, AI Research, Meta
프론티어 AI 역량은 빠르게 발전하고 있으며, 그 발전 속도 자체도 가속화되고 있다.
Frontier AI capabilities are advancing rapidly, and the pace of progress is itself accelerating.
우리는 평가(evaluation) 작업에서 이를 직접 확인한다. CyberGym과 ExploitGym은 프론티어 AI 에이전트가 이제 실제 소프트웨어 취약점을 발견하고 악용할 수 있음을 보여준다. 적절한 안전장치가 없다면 이는 대규모 사이버 공격을 가능하게 할 수 있다.
We see this directly in our evaluation work. CyberGym and ExploitGym show that frontier AI agents are now capable of discovering and exploiting real-world software vulnerabilities, which without appropriate safeguards, could enable cyberattacks at scale.
또한 많은 연구자는 재귀적 자기 개선(RSI)이 향후 몇 년 내에 실현될 가능성이 있다고 본다. 이는 우리가 이러한 시스템을 이해하고 거버넌스할 수 있는 능력을 앞지르는 방식으로 발전을 가속할 수 있다.
Many researchers also consider recursive self-improvement (RSI) plausible within the next few years, accelerating progress in a way that could outpace our ability to understand and govern these systems.
의도적 속도 조절(deliberate pacing)은 강압적이고 잠재적으로 극단적인 조치이며, 우리에게 결코 필요하지 않을 수도 있다. 그러나 만약 필요하게 된다면, 위기 한가운데에서 이를 안전하게 고안해 낼 수는 없다. 이는 잘 설계하기가 매우 어렵고, 잘못 시행하면 득보다 피해가 더 클 수 있다. 성공적인 조정 프레임워크라면 반드시 증거 기반이어야 한다. 즉, 실제 위험을 포착하지 못하면서 혁신을 저해하는 자의적 임계값을 피하고, 대신 엄밀하고 측정 가능한 위험 평가(assessment)에 근거해야 한다. 여느 핵심 기반시설과 마찬가지로, 이는 필요해지기 전에 연구되고, 시험되고, 구축되어야 한다. 이것이 우리가 기다리지 말고 지금 이를 신중하게 설계해야 하는 이유이다.
Deliberate pacing is a heavy-handed and potentially extreme measure, and we may never need it. But if we do, it cannot be safely invented in the middle of a crisis. It is very difficult to design well, and if done poorly could do more harm than good. Any successful coordination framework must be evidence-based, avoiding arbitrary thresholds that fail to capture true risk while stifling innovation, and instead be grounded in rigorous, measurable assessments of risk. Like any critical infrastructure, it must be researched, tested, and built before it is needed. This is why we must carefully design it now, rather than waiting.
이러한 역량은 국제적이고 측정 가능해야 한다. 국제적이어야 하는 이유는 다른 모두가 앞다투어 달려가는 프론티어의 속도를 어느 한 랩이나 국가가 단독으로 조절할 수 없기 때문이다. 측정 가능해야 하는 이유는 효과적인 거버넌스를 위해서는 프론티어 AI 시스템에 대한 엄밀하고, 투명하며, 검증 가능한 평가(evaluation)가 필요하기 때문이다.
Such a capability must be international and measurable: international because no single lab or country can pace a frontier everyone else is racing toward; measurable because effective governance requires rigorous, transparent, and verifiable evaluations of frontier AI systems.
우리는 의도적 속도 조절이 필요해질지, 또는 언제 필요해질지 알지 못한다. 그러나 기술적·거버넌스 도구와 국제 협력 프레임워크를 포함한 역량을 지금 구축해 두면, 사회는 귀중한 선택지(optionality)를 확보하게 된다. 효과를 거두려면 이 역량은 결정적인 순간이 오기 전에 마련되어 있어야 한다. 프론티어가 움직이는 속도를 고려하면, 그 순간은 우리가 예상하는 것보다 빨리 올 수도 있다.
We do not know if, or when, deliberate pacing will become necessary. But building the capacity now, including technical and governance tools and an international cooperation framework, gives society valuable optionality. To be effective, this needs to exist before the decisive moment arrives. At the speed the frontier is moving, that moment may arrive sooner than we expect.
역량을 구축하는 것은 그것을 언제 사용할지, 또는 사용할지 여부를 결정하는 것과 같지 않다. 후자는 각별한 신중함, 엄밀한 증거, 그리고 폭넓은 국제적 합의를 필요로 한다. 그러나 도구가 마련되어 있지 않다면 선택의 여지 자체가 없을 것이다.
Building the capacity is not the same as deciding when, or whether, to use it. The latter requires great caution, rigorous evidence, and broad international consensus. But without tools in place, there will be no choice at all.
역량은 위기 중에 신뢰성 있게 구축될 수 없다. 위기 전에 대비하는 것이 신중한 길이다.
Capabilities cannot be reliably built during a crisis. Preparing before a crisis is the prudent path.
Jason Wolfe
Jason Wolfe
기술 스태프, OpenAI
Member of Technical Staff, OpenAI
OpenAI는 인간이 AI 개발에 대한 통제를 유지해야 하며, 발전 속도에 관한 결정은 개별 랩에 맡겨 둘 것이 아니라 민주적 절차를 통해 내려져야 한다고 밝힌 바 있다. 나는 이에 강력히 동의한다.
OpenAI has said that humans should remain in control of AI development, and that decisions about the pace of progress should be made through democratic processes rather than left to individual labs. I strongly agree.
발전은 이미 매우 빠르게 진행되고 있다. 기본적으로 경쟁 압력은 가장 빠르게 움직이고 가장 큰 위험을 감수하려는 기업이나 국가에 보상을 준다. 재귀적 자기 개선은 이러한 역학을 극적으로 가속할 수 있으며, 잠재적으로는 발전을 이해하고, 위험을 평가(assessment)하며, 의미 있는 인간 감독을 유지하는 우리의 집단적 능력을 넘어설 수도 있다.
Progress is already moving very quickly. By default, competitive pressure rewards whichever company or country is willing to move fastest and accept the most risk. Recursive self-improvement could dramatically accelerate those dynamics, potentially beyond our collective ability to understand progress, assess risks, and maintain meaningful human oversight.
우리는 프론티어 학습, 내부 배포, 발전 속도, 그리고 점점 더 유능해지는 시스템과 관련된 위험 및 안전장치에 대해 국내 차원의 투명성을 강화하는 것에서부터 시작해야 한다. 대중과 정책 입안자가 결정을 내리는 데 필요한 정보를 갖추지 못한다면 민주적 결정은 불가능하다.
We should start with stronger domestic transparency about frontier training, internal deployment, the pace of progress, and the risks and safeguards associated with increasingly capable systems. Democratic decisions are impossible if the public and policymakers don’t have the information they need to make them.
그러나 투명성만으로는 국제적 경쟁을 해결할 수 없다. 우리는 신뢰할 수 있고 검증 가능한 국제 조정을 위한 기술적·거버넌스 역량도 구축해야 한다. 어쩌면 우리는 그것을 결코 사용할 필요가 없을지도 모른다. 그러나 많은 전문가가 향후 2년 내에 지능 폭발(intelligence explosion)이 일어날 가능성이 있다고 보는 상황에서, 나는 지금 이 역량을 구축하기 시작하는 것이 시급하다고 생각한다.
But transparency alone won’t solve an international race. We also need to build the technical and governance capacity for credible, verifiable international coordination. Maybe we never need to use it. But with many experts considering an intelligence explosion plausible within the next two years, I think it's urgent that we start building this capacity now.
Ethan Perez
Ethan Perez
정렬 팀 리드, Anthropic
Alignment Team Lead, Anthropic
현재의 AI 발전 속도에서 AI 기업의 안전 팀들은 몇 달마다 사회에 대한 새로운 위험을 막기 위해 전력 질주해야 한다. 언젠가는 해결하는 데 더 많은 시간이 필요한 문제에 부딪히게 될 것이다.
With the current rate of AI progress, safety teams at AI companies have to sprint to prevent new risks to society every few months. At some point, we’re going to hit problems we need more time to solve.
Danny Sawyer
Danny Sawyer
선임 연구 과학자, 프론티어 AI, Google
Senior Research Scientist, Frontier AI, Google
나는 AI 개발 속도를 의도적으로 조절하려는 시도가 극도로 어려울 것이며, 적절한 주의 없이 이루어진다면 득보다 실이 클 수 있다고 생각한다. 그럼에도 이 성명서에 서명하는 이유는, 속도 조절 시도가 실제로 이루어진다면 위기에 대한 대응으로 갑작스럽게 시행되기보다는 체계적으로 연구되고 계획된 것이 더 낫기 때문이다.
I believe that attempting to deliberately pace AI development will be extremely difficult, and could do more harm than good if done without proper care. However, I am signing this statement because, if an attempt at pacing does occur, it would be better for it to have been methodically researched and planned rather than suddenly implemented as a reaction to a crisis.
David Clyde
David Clyde
기술 스태프 - 사전학습, OpenAI
Member of Technical Staff - Pretraining, OpenAI
현재 나는 가까운 미래의 협상된 감속을 포함하지 않는 모든 경로에 대해 상당한 두려움을 느낀다. 또한 세계가 충분히 빠르게 감속을 협상하고 개시할 수 있을지에 대해서도 우려하지만, 이 성명서에 대한 폭넓은 동의를 보여 주는 것은 가치 있는 한 걸음으로 보인다.
I currently feel quite afraid of all paths I see that don't include a near-future negotiated slowdown. I'm also worried about the world's chances of negotiating+initiating a slowdown fast enough, but demonstrating broad agreement on this statement seems a valuable step.
Joshua Achiam
Joshua Achiam
OpenAI
OpenAI
자동화된 AI 연구개발(R&D)을 이해하고 경우에 따라 그 속도를 조절할 수 있도록 미국 정부가 역량을 강화해야 하는 대상으로 그것이 옳은지, 혹은 그것만이 유일한 대상인지, 그리고 그러한 도구가 어떤 형태를 띠어야 하는지는 알지 못한다. 그러나 이는 진지하게 고려할 가치가 있다. 다만 나는 그러한 거버넌스 도구가 광범위하거나 과도하지 않기를 바란다. 그럼에도 많은 프론티어 AI 역량은 이중 용도를 지니고 있어 현 시점에서 속도 조절이 정당화될 수 있다.
I don't know what form such tools should take, nor whether automated AI R&D is the right or only thing that the U.S. government should develop increased capacity to understand and possibly pace, but this is worth serious consideration; however I hope such governance tools will not be expansive or excessive. But many frontier AI capabilities are dual use in a way that may justify pacing at this point.
Jeff Klingner
Jeff Klingner
선임 소프트웨어 엔지니어, Google
Senior Software Engineer, Google
이것이 공유 지식(common knowledge)이 되는 순간, 즉 중국과 미국, 그리고 여러 랩에 있는 우리 모두가 나머지 모든 이들도 속도를 늦춰야 한다고 생각한다는 사실을 알게 되는 순간, 비로소 공조가 가능해진다.
Once this becomes common knowledge - once all of us in China & the US and at the various labs see that all the rest of us also think we need to slow this down - that's when coordination becomes possible.
Jeremy Hadfield
Jeremy Hadfield
기술 스태프, Anthropic
Member of Technical Staff, Anthropic
나는 현재 AI 역량 개발 속도가 *아직* 위험하다고 생각하지는 않지만, 필요할 경우를 대비해 속도를 늦출 수 있는 선택지를 갖는 것은 중요하다. 더욱이 향후 몇 년간 AI 연구개발(R&D)이 가속되면 발전 속도가 위험해질 수 있다. 나는 AI의 끊임없는 발전 속도로 인해 사회가 따라잡기 어려워지고, 랩들이 안전에서 편법을 쓰도록 압박받는 모습을 보아 왔다. 그러나 현재 프론티어 AI 랩들은 효과적으로 공조하지 못한다. 속도를 늦출 수 있는 선택지를 갖는 것은 당연한 일이다.
While I don't believe the pace of current AI capabilities development is *yet* dangerous, it's important to have the option to slow down in case we need it. Further, accelerating AI R&D over the next couple years could make the pace of progress dangerous. I've seen how the relentless pace of AI makes it hard for society to keep up and how it puts pressure on labs to cut corners on safety. However, currently frontier AI labs can't coordinate effectively. It's a no-brainer to have the option to slow down.
Jon Wolverton
Jon Wolverton
선임 소프트웨어 엔지니어, Google
Senior Software Engineer, Google
업계 리더 대부분이 상황이 끔찍하게 잘못될 수 있다는 가능성을 불편할 정도로 높게 보고 있음에도, 모든 AI 랩이 경쟁에 얽매여 파국적 위험에 대한 작업을 최소화하고 있는 것처럼 느껴진다. 이것은 그냥 켜고 끌 수 있는 스위치가 없는 기술이며, 다른 누구에게만큼이나 그 창조자에게도 쉽게 큰 손해를 입힐 수 있다. 비상시에 랩들이 속도를 늦추거나 플러그를 뽑을 수 있게 하는 프레임워크가 있다면 우리 모두 밤에 조금 더 편히 잠들 수 있을 것이다.
It feels like all the AI labs are constrained by competition to minimize their work on catastrophic risks, even though most industry leaders have an uncomfortably high probability that things could go terribly wrong. This is a technology that doesn't have an off switch you can just flip, and it could easily do as much damage to its creators as to anyone else. Having a framework to allow labs to slow down or pull the plug in case of emergency will help us all sleep a bit better at night.
Laura Weidinger
Laura Weidinger
스태프 연구 과학자, Google
Staff Research Scientist, Google
AI가 전기만큼 변혁적일 것이라는 말이 사실이라면, 우리는 AI가 세상에 도입되는 방식에 대해 의도적이어야 한다. 거버넌스, 안전, 또는 기술이 공익에 봉사한다는 보장 없이 무분별하게 벌어지는 경쟁은 그러한 의도성을 가로막는다.
If it's true that AI will be as transformational as electricity, we better be intentional about how it is introduced to the world. A mindless race without assurances on governance, safety or the technology serving the public interest stands in the way of such intentionality.
Michael Tontchev
Michael Tontchev
스태프 엔지니어, 안전성 평가 플랫폼 리드, Meta
Staff Engineer, Lead for Safety Evals Platform, Meta
초인적 AI는 머지않아(3~10년 내에) 도래할 가능성이 높다. 기술적 통제와 거버넌스가 인간이 계속 통제권을 유지하도록 해 줄 수도 있지만, 이들은 제때 준비될 궤도에 있지 않다. 초지능을 상대로 체스를 둔다고 생각해 보라. 그것을 능가하게 해 줄 기적 같은 통찰은 떠오르지 않을 것이다. 그저 지게 될 것이다. 그리고 통제를 벗어난 초지능이 만들어진다면, 그 게임은 체스가 아닐 것이다.
Superhuman AI is likely to arrive very soon (within 3-10 years). Technical controls and governance might allow humans to remain in control of it, but they're not on track to be ready. Think of it as playing chess against a superintelligence. You won't have a miraculous insight that lets you outsmart it. You will just lose. And if a rogue superintelligence is created, the game won't be chess.
Saul Reynolds-Haertle
Saul Reynolds-Haertle
기술 스태프, Anthropic
Member of Technical Staff, Anthropic
_모두가_ 하지 않는 한 우리는 이것을 할 수 없다. 이는 전 세계적이어야 한다. 지금 우리에게는 그렇게 할 방법이 없다. 우리 _모두가_ 속도를 늦출 수 있는 방법을 구축해야 한다.
We can't do this unless _everyone_ does. It needs to be global. Right now we have no way to do that. We need to build a way for us to _all_ slow down.
Stephanie Chan
Stephanie Chan
스태프 연구 과학자, Google
Staff Research Scientist, Google
나는 10년 동안 AI 분야에서 일해 왔다. 지난 몇 년간 몇 달마다, 아무리 자주 예측을 갱신해도 기술이 얼마나 빠르게 발전하는지에 거듭 놀라곤 했다. AI는 결국 사회와 국가가 적응할 수 있는 속도보다 훨씬 빠르게 발전할 수도 있다. 그래서 DeepMind CEO인 Demis Hassabis를 비롯한 AI 분야의 많은 저명한 리더들이 속도를 늦출 수 있는 능력을 공개적으로 지지해 왔다. 동시에 공조는 경쟁 역학과 반독점 규제를 포함한 여러 요인에 의해 저해되고 있다. 나는 전 세계의 국가와 사회가 이 강력한 기술에 신중하게 대비하고 적응할 시간을 확보할 수 있도록, 취할 수 있는 행동의 범위에서 더 큰 *선택 가능성(optionality)*을 지지하기에 (개인 자격으로) 이 성명서에 서명했다.
I have worked in AI for a decade. Every few months in the last years, I have found myself surprised again and again at how rapidly the technology advances, no matter how often I update my predictions. AI may end up progressing far more quickly than societies and states can adapt. Thus, many prominent leaders in AI have publicly supported the ability to slow down, including DeepMind CEO Demis Hassabis. At the same time, coordination is hampered by multiple factors, including competitive dynamics and antitrust regulations. I signed this statement (in a personal capacity) because I support greater *optionality* in the range of actions available, to ensure that states and societies around the world have time to thoughtfully prepare and adapt to this powerful technology.
Alex Zhao
Alex Zhao
연구 과학자, OpenAI
Research Scientist, OpenAI
내 의견으로는 미국 랩 간의 공조는 실현 가능하고 잠재적으로 간단할 수도 있지만, 훨씬 더 크고 중대한 위협은 중국과의 지정학적 군비 경쟁에서 비롯된다. 맨해튼 프로젝트가 대기 중의 산소 전체를 점화시킬 수도 있다고 생각하면서도 결국 시험 폭발을 강행했던 것처럼, 나는 향후 지정학적 경쟁으로 인해 행위자들이 이 국제 군비 경쟁이라는 명목하에 끔찍할 정도로 과도한 안전 위험을 감수하게 될까 두렵다. 그 결과 적절한 안전장치 없는 배포로 인해 파국적인 부작용이 발생할 수 있으며, 이는 핵심 기반시설의 파괴나 인류의 전반적인 무력화(disempowerment)로 이어질 수 있다.
My opinion is that while coordination between American labs is feasible and could potentially be straightforward, the much larger and more significant threat is from a geopolitical arms race with China. Much as the Manhattan Project thought they might ignite all of the oxygen in the atmosphere but chose to run a test detonation anyways, I’m afraid that due to future geopolitical competition, actors will take terribly excessive safety risks in the name of this international arms race. As a result there could be catastrophic side effects from deployment without due safeguards, potentially resulting in the destruction of key infrastructure or the general disempowerment of humanity.
Luke Drago
Luke Drago
Thinking Machines
Thinking Machines
감속이나 중단을 위한 많은 제안은 권력을 집중시킨다. 즉, AI에 대한 통제권을 소수의 손에 집중시키고 우리를 더 나쁜 처지에 놓이게 한다. 나는 우리가 더 잘할 수 있다고 생각한다. 내가 서명하는 이유는 향후 AI 발전을 조율하기 위한 메커니즘이 필요할 수 있다고 믿기 때문이며, 위기 속에서 이를 만들어 내는 것은 나쁜 메커니즘을 얻는 확실한 길이다. 한 행위자가 미래를 소유하지 못하게 하는 공조 메커니즘을 구축하려면 좁은 회랑을 따라 길을 헤쳐 나가야 하며, 그 작업에 일찍 착수할수록 좋다.
Many proposals for a slowdown or pause concentrate power — they centralize control of AI into a few hands and leave us worse off. I think we can do better. I’m signing because I believe we may need mechanisms to coordinate AI progress in the future, and inventing it in a crisis is a sure way to get a bad mechanism. We have to tread a path through a narrow corridor if we want to build coordination mechanisms that don’t let one actor own the future, and the earlier we can get to work on that the better.
Xerxes Dotiwalla
Xerxes Dotiwalla
나는 고역량(Highly capable) AI가 인류에게 매우 좋게 될 수도, 매우 나쁘게 될 수도 있다고 믿기에 인공일반지능 안전과 정렬에 경력을 바쳤다. 우리는 AI가 올바르게 행동하는지 시험할 수 있다. 그러나 정작 중요한 순간에도 AI가 계속 올바르게 행동할지는 아직 시험할 수 없다. 이것이 바뀌기 전까지 우리에게는 AI 역량 증가의 감속을 공조할 수 있는 선택지가 필요하다.
I dedicated my career to AGI safety and alignment because I believe highly capable AI can go very well or very badly for humanity. We can test whether an AI behaves well. We cannot yet test whether it will keep behaving well when it matters. Until that changes, we need the option to coordinate a slowdown in AI capability growth.
Swante Scholz
Swante Scholz
나는 우리 회사가 AI로 인한 파국적 위험 또는 실존적 위험의 가능성을 훨씬 높이는 AI 경쟁 역학에 기여하고 있는 것은 아닌지 우려한다. 여기서 제시된 프론티어의 속도 조절 제안은 이러한 위험을 줄이기 위한 매우 합리적인 노력으로 보인다.
I worry my company is contributing to AI race dynamics that make catastrophic or existential risks from AI much more likely. The proposal here for pacing the frontier seems like a highly reasonable effort to reduce these risks.
Andrew Stewart
Andrew Stewart
매니저, Anthropic
Manager, Anthropic
상황은 빠르게 움직이고 있을 뿐 아니라 가속되고 있으며, 우리의 미래는 현재 아무런 제한이 없는 경쟁에 의해 형성되고 있다.
Things are not only moving fast but accelerating and our future is getting shaped by a race that currently has no limits.
Brandon Houghton
Brandon Houghton
OpenAI
OpenAI
나는 인류가 프론티어 AI에 대한 통제권을 유지하는 것을 지지하지만, 그 방법에 대해서는 신중해야 한다. 거버넌스가 공개 모델에만 적용된다면, 최첨단 역량이 독립적 검증이 미치지 않고 선택된 소수만 접근할 수 있는 비공개 또는 특수 시스템으로 밀려날 위험이 있다. 이는 위험을 의미 있게 줄이지 못한 채 권력을 집중시킬 수 있다. 효과적인 감독은 민감 데이터를 보호하면서도 측정 가능하고, 검증 가능하며, 공개 개발과 비공개 개발 모두에 적용 가능해야 한다. 그렇지 않으면 우리는 프론티어를 늦추지 못한 채 접근만 늦추게 될 수 있다.
I support keeping humanity in control of frontier AI, but we need to be thoughtful about how we do it. If governance only applies to public models, we risk pushing the most advanced capabilities into private or specialized systems, beyond independent scrutiny and accessible only to a select few. That could concentrate power without meaningfully reducing risk. Effective oversight must be measurable, verifiable, and applicable across public and private development, while protecting sensitive data. Otherwise, we may slow access without slowing the frontier.
Chang Sun
Chang Sun
기술 스태프, OpenAI
Member of Technical Staff, OpenAI
나는 책임 있는 배포를 가능하게 하고 바닥으로의 경쟁 가능성을 피하기 위한 국제 거버넌스 메커니즘을 구축하는 것이 본질적으로 가치 있다고 생각한다. 모든 랩과 국가가 다른 행위자들이 무엇을 할지에 대한 두려움 때문에 최대한 빠르게 움직이는 것은, 개별 행위자들이 속도와 안전 사이에서 위험한 절충을 하도록 쉽게 유인하는 방식으로 보인다.
I think it's inherently valuable to build international governance mechanisms to enable responsible deployment and avoid a possible race to the bottom. All labs and countries moving as fast as possible out of fear of what other actors will do seems like an easy way to incentivize individual actors to make dangerous tradeoffs between speed and safety.
Dylan Moore
Dylan Moore
로보틱스, OpenAI
Robotics, OpenAI
나는 필요할 때 사회가 AI 개발 속도를 책임 있게 조절할 수 있는 선택지를 제공하는 도구를 개발한다는 목표를 지지한다. 동시에 미국은 AI 분야에서 우위를 유지해야 하며, 경쟁자들이 계속 전진하는 동안 개발을 늦추는 것은 피해야 한다. 안전을 개선하고, 경제적·사회적 영향을 이해하거나, 감독을 강화하기 위한 시간을 벌려는 의미 있는 노력이라면 궁극적으로 국제적으로 공조되고, 집행 가능하며, 악의적 행위자나 비참여국이 우위를 점하지 못하도록 설계되어야 할 것이다.
I support the goal of developing tools that give society the option to responsibly pace AI development when necessary. At the same time, the United States should maintain its edge in AI and avoid slowing development while competitors continue to advance. Any meaningful effort to buy time to improve safety, understand economic and social impacts, or strengthen oversight will ultimately need to be internationally coordinated, enforceable, and designed to prevent bad actors or non-participating countries from gaining an advantage.
Francesca Surraco
Francesca Surraco
Anthropic
Anthropic
AI 시스템은 안전, 노동시장, 민주적 제도, 환경에 위험을 초래하며, 이러한 위험은 업계의 자발적 약속에만 맡겨 두기에는 너무나 중대하다. 너무 늦기 전에, 지금 당장 프론티어 AI 개발과 배포에 대한 구속력 있는 규제 감독이 필요하다. 이 기술은 지구와 그 위의 모든 이에게 이로움을 줄 막대한 잠재력을 지니고 있지만, 적절한 규제 없이는 그 잠재력이 결실을 맺지 못할 것이다.
AI systems carry risks to safety, to labor markets, to democratic institutions, to the environment that are too consequential to be left to voluntary industry commitments alone. We need binding regulatory oversight of frontier AI development and deployment now, before it's too late. This technology holds enormous potential to benefit the planet and everyone on it, but that potential won't come to fruition without proper regulation.
Grace Atwood
Grace Atwood
기술 스태프, Anthropic
Member of Technical Staff, Anthropic
업계 전반에서 AI 경쟁의 상업적 압력은 계속 누적되며 모두를 점점 더 빠른 속도로 몰아붙이고 있다. 한편 안전은 선의에서 비롯되었으나 사후 대응적이고 일시적인 관심을 받을 뿐, 곧바로 다시 경쟁으로 돌아간다. 속도를 늦춘다는 것은 연구개발의 속도를 줄인다는 뜻이 아니라, 업계 차원에서 의도적으로 우리 역량의 더 많은 부분을 안전 연구로 돌린다는 뜻이다. 안전을 경쟁의 일부로 만들어야 한다.
Across the industry, commercial pressures in the AI race continue to compound, urging everyone forward at increasing speed. Meanwhile, safety receives reactionary, well intentioned, momentary attention before it's right back to the race again. Slow down does not mean decrease pace of research and development but rather intentionally, as an industry, redirect more of our capabilities towards safety research. Make safety part of the race.
Grant Birkinbine
Grant Birkinbine
기술 스태프 - 보안, OpenAI
Member of Technical Staff - Security, OpenAI
AI 개발을 가속하는 AI는 막대한 이익을 가져올 수 있지만, 동시에 새로운 위험을 이해하고 대응할 수 있는 시간을 압축한다. AI가 진정으로 인류 전체에 이로움을 주려면, 우리가 올바른 선택을 할 수 있도록 AI가 안전하게 개발(또는 속도 조절)되도록 보장하는 국제 공조와 메커니즘이 필요하다.
AI that accelerates AI development could unlock enormous benefits, but it also compresses the time we have to understand and respond to new risks. If AI is truly going to benefit all of humanity, we need international coordination and mechanisms that ensure AI is developed (or paced) safely, so we can make the right choices.
Jason Bohrer
Jason Bohrer
연구원, 안전, Meta
Researcher, Safety, Meta
AI는 인류 전체에 이로움을 줄 급속한 기술 발전을 가능하게 할 잠재력을 지니고 있지만, AI 기반 사이버 공격, 화학·생물·방사능·핵·폭발물(CBRNE), 통제 상실의 위험은 실재한다. 우리는 AI 안전이 AI 역량과 보조를 맞춰 발전하도록 보장해야 하며, 이는 국제 공조를 통해서만 가능할 것이다.
AI has the potential to enable rapid technological advancement that will benefit all of humanity, but the risks of AI-powered cyberattacks, CBRNE, and loss of control are real. We must ensure that we advance AI safety in lockstep with AI capabilities, which will only be possible through international coordination.
Joe Carlsmith
Joe Carlsmith
기술 스태프, Anthropic
Member of Technical Staff, Anthropic
AI 개발 속도를 의도적으로 조절하는 것에 대한 내 견해를 자세히 밝힌 글은 다음 에세이를 참고하라: https://joecarlsmith.com/2026/03/19/on-restraining-ai-development-for-the-sake-of-safety/
For a detailed statement of my views about deliberately pacing AI development, see this essay: https://joecarlsmith.com/2026/03/19/on-restraining-ai-development-for-the-sake-of-safety/
Joseph Krisciunas
Joseph Krisciunas
OpenAI
OpenAI
내 지지는 다소 양가적이다. 나는 규제 포획에 단호히 반대하며, 어떤 정부든 이토록 강력한 기술을 어떻게 사용할지에 대해 깊이 경계한다. 동시에 정부는 앞으로 다가올 일을 이해하고 시민의 최선의 이익을 위해 행동할 필요가 있다.
A bit of a conflicted endorsement from me. I’m firmly opposed to regulatory capture and deeply wary of how any government might use technology this powerful. At the same time, governments need to understand what’s coming and act in their citizens’ best interests.
Kim Stachenfeld
Kim Stachenfeld
스태프 연구 과학자, Google
Staff Research Scientist, Google
나는 AI를 둘러싼 국제 협력을 구축하려는 노력을 지지하기 때문에 서명한다. 또한 잠재적으로 위험 부담이 큰 맥락에서 대규모로 적용하고 있는 기술의 결과를 이해하는 것이 중요하다고 믿는다.
I am signing because I support efforts to build international cooperation around AI, and believe it's important to understand the consequences of technology we are applying at massive scale in potentially high stakes contexts.
Klaudia Krawiecka
Klaudia Krawiecka
보안 엔지니어, 프론티어 위험 평가(evaluation), Meta
Security Engineer, Frontier Risk Evals, Meta
세상을 개선할 AI의 잠재력은 실재하지만, 이는 그 역량에 보조를 맞추는 보안 및 감독 메커니즘을 구축할 때에만 가능하다. 나는 우리가 미래 세대에게 단지 속도만이 아니라 의도를 가지고 배포된 기술을 물려줄 책무가 있다고 믿기에 서명했다.
AI's potential to improve the world is real, but only if we build the security and oversight mechanisms that keep pace with its capabilities. I signed because I believe we owe future generations a technology that was deployed with intention, not just speed.
Luke Bennett
Luke Bennett
기술 스태프(매니저), Anthropic
Member of Technical Staff (Manager), Anthropic
걸려 있는 것이 너무 많고, 잘못될 수 있는 것도 너무 많으며, 우리가 이것을 제대로 해내지 못한다면 매우 암울한 미래가 우리 앞에 놓여 있다. 함께 속도를 늦춘다고 해서 잃을 것은 없다.
There is too much on the line, too much that can go wrong and a very dark future ahead of us if we don’t get this right. There is nothing to lose from collectively slowing down.
Michael Thiessen
Michael Thiessen
소프트웨어 엔지니어, Google
Software Engineer, Google
중국은 안전과 거버넌스에 관해 협력하고자 하는 의사를 밝혀 왔다. 미래가 인간의 것으로 남도록 보장하기 위해 중국과 함께 노력하자.
China has indicated a desire to collaborate on safety and governance, let's work with them to ensure the future remains human.
Patryk Grzelak
Patryk Grzelak
기술 스태프, Anthropic
Member of Technical Staff, Anthropic
기술 개발이 우리의 지속적 생존을 담보로 한 맹목적 믿음을 요구해서는 안 된다.
Developing technology shouldn't require a leap of faith for our continued survival.
Prakash Murugesan
Prakash Murugesan
연구 엔지니어, Meta
Research Engineer, Meta
재귀적 자기 개선(RSI)의 위험이 더 이상 먼 미래의 우려가 아니라는 것은 분명하다. 그 위험은 이미 지금 여기에 있다. 안전에 필요한 가드레일은 어느 한 민간 주체에 맡길 수 없으며, 대중에게 책임을 지는 학식 있는 과학자, 엔지니어, 정부 지도자들의 협의체가 결정해야 한다. 그래야 인류의 최악이 아닌 최선의 부분에 부합하는 미래를 만들 수 있다.
It's clear that the risks of RSI are no longer a concern for the distant future. They are here now. The guardrails necessary for safety cannot be entrusted to any single private entity but should be decided by a consortium of learned scientists, engineers, and leaders in government accountable to the public so that we build a future that is aligned with the best parts of humanity and not its worst.
Praneet Rathi
Praneet Rathi
Anthropic
Anthropic
인간의 역량 강화를 지키고 사이버 보안 및 화학·생물·방사능·핵(CBRN) 같은 분야의 위험을 줄이면서 AI의 모든 이점을 누리려면, 국내외 프론티어 랩 간의 공조가 필요하다. 민주적으로 선출된 미국 정부는 이러한 공조를 관리하는 데 결정적인 역할을 하게 될 것이며, 나는 이 문제에 대한 정부의 관심을 더 끌어내려는 이 노력을 지지한다.
For us to experience all the benefits of AI while preserving human empowerment and reducing the risk in fields like cybersecurity and CBRN, we need coordination between frontier labs in and outside the country. The democratically elected US government would have a crucial role to play in administering this coordination and I support this effort to get more government attention on this matter.
Toby Scales
Toby Scales
CISO, 미디어 & 엔터테인먼트 @ Google Cloud, Google
CISO, Media & Entertainment @ Google Cloud, Google
AI는 변혁적 기술이며, 우리는 그 변혁이 오로지 자본시장의 요구에 의해서만 형성되도록 내버려 두어서는 안 된다.
AI is a transformative technology, and we must not let the transformation be shaped solely by the demands of capital markets.
William Li
William Li
연구원, OpenAI
Researcher, OpenAI
역사는 기술을 만들어 내는 것만으로는 그 이익이 사람과 지구를 위해 쓰이도록 보장하기에 충분하지 않았음을 보여 준다. AI의 변혁적 잠재력을 온전히 실현하려면, 세계 각국 시민의 민주적 참여가 AI의 안전하고 공평한 발전을 이끌어야 한다.
History shows that the mere creation of technology has not been enough to ensure its benefits go toward the benefit of the people and the planet. To unlock AI’s full transformative potential, the democratic engagement of international peoples must steer its safe and equitable development.
Eider Oliveira
Eider Oliveira
수석 엔지니어, Google
Principal Engineer, Google
이것은 인류에게 중요한 단계이며, 서둘러 뛰어들어서는 안 된다. 우리는 인류의 가치와 목표를 지키면서 처음부터 끝까지 우리가 통제권을 쥐고 있으며 앞으로도 그러할 것임을 확실히 해야 한다.
This is an important step for humanity, we should not rush into it. We need to make sure we are and will be in control all the way, preserving humanity values and goals.
Alex Cloud
Alex Cloud
기술 스태프, Anthropic
Member of Technical Staff, Anthropic
1년 전만 해도 나는 직접 코드를 작성했고, Claude를 이용해 추가할 내용을 제안받거나 질문에 대한 답을 찾았다. 이제 나는 코드를 작성하지 않는다. Claude에게 고수준의 지시를 내리면, Claude는 내가 혼자서는 결코 달성할 수 없었을 속도로 아이디어를 검증하는 실험을 대신 수행한다. 나는 이러한 추세가 계속될 것으로 예상하며, 어쩌면 AI 개발이 오늘날보다 극적으로 빨라지고 인간의 입력이 거의 개입하지 않는 지점에까지 이를 수도 있다. 나는 세상이 이러한 가능성에 대비되어 있지 않다고 생각한다. 해결책이 존재한다고 낙관하지만, 그 해결책에는 사려 깊은 AI 거버넌스가 필요할 것이다. AI 기업 간의 경쟁만으로 그것이 어떻게 나올 수 있을지 나는 알지 못한다.
A year ago, I wrote my own code and used Claude to propose additions and find answers to my questions. Now, I don’t write code. I give high-level instructions to Claude and it runs experiments to test ideas for me at a pace I never could have achieved on my own. I expect this trend to continue, possibly to a point where AI development is dramatically faster than today and involves almost no human input. I don’t think the world is ready for this possibility. I’m optimistic that a solution exists, but that solution will require thoughtful AI governance. I don’t see how it can arise from competition between AI companies alone.
Lauren Deason
Lauren Deason
머신러닝 엔지니어, 평가(evaluation), Meta
Machine Learning Engineer, Evaluations, Meta
"AI 개발 프론티어의 속도를 의도적으로 조절할 수 있는 능력"이 무엇을 의미하는지 훨씬 더 명확히 할 필요가 있겠지만, 나는 이를 정의하기 위한 국제 협력을 지지한다.
Much more clarity will be needed on what is meant by the “ability to deliberately pace the frontier of AI development”, but I am supportive of international cooperation to define this.
Mathieu Lariviere
Mathieu Lariviere
기술 프로젝트 매니저 및 연구 지원 코디네이터, Meta
Technical Project Manager & Research Support Coordinator, Meta
인공지능은 오늘날의 차별 및 프라이버시 침해에서부터 고도화된 시스템에 대한 인간의 통제 상실, 생물학 및 사이버 역량의 무기화, 돌이킬 수 없는 권력 집중을 포함한 전례 없는 파국적 위협에 이르기까지 다양한 스펙트럼의 위험을 제기한다. 그럼에도 전 세계적으로 이러한 위험을 줄이는 일에 전업으로 종사하는 사람은 10 000명도 되지 않으며, 업계의 "핵심 구조적 약점"은 여전히 "초지능" AI 시스템을 통제하기 위한 신뢰할 만한 계획이 전혀 없다는 점이다. 현재 시행되고 있는 통제 지점은 쉬운 것들뿐이다. 경쟁 구조는 어떤 대가를 치르더라도 역량을 기하급수적으로 발전시키도록 부추기는 반면 거버넌스는 선형적으로 발전하기 때문에, 역량과 거버넌스 간의 격차는 커지고 있다. 즉, 문제는 가장 필요한 것들이 바로 현재의 인센티브 구조가 가장 만들어 내지 못하는 것들이라는 점이다. 향후 5년이 결정적인 시기이다.... 위험을 해결하는 일은 근본적으로 지식의 문제가 아니라 조정의 문제이다.
Artificial intelligence poses a spectrum of risks ranging from present-day discrimination and privacy violations to unprecedented catastrophic threats including loss of human control over advanced systems, weaponization of biological and cyber capabilities, and irreversible concentration of power. Despite this, fewer than 10 000 people work full-time on reducing these risks globally, and the industry's "core structural weakness" remains the complete absence of credible plans for controlling "superintelligent" AI systems. The control points being implemented are the easy ones. The gap between capabilities and governance is growing because the competitive framework encourages the exponential advancement of capabilities at all costs, while governance advances linearly. i.e., the problem is that the things most needed are the things our current incentive structures are worst at producing. The next five years are the critical window.... Solving the risks is fundamentally a coordination problem, not a knowledge problem.
모든 개인은 영향력을 지닌다. 모든 개인은 이러한 기술의 올바른 개발과 사용을 지켜 나갈 책임이 있으며, 자존심을 넘어서 이에 대한 책임을 물을 책임이 있다.
Every individual has an impact. Every individual has a responsibility to uphold the right development and use of these technologies; and, to hold this accountable beyond ego.
*통상적 면책 고지: 나는 회사를 대변하지 않는다는 점에 유의하기 바란다. 위에 표명된 의견은 전적으로 나 개인의 것이며, 회사는 이에 대해 책임을 지지 않는다.
*Typical Disclaimer: Note that I do not speak for the company. The opinion expressed above is strictly my own, and that the company may not be held accountable for this.
Nate Kratzer
Nate Kratzer
데이터 과학자, Meta
Data Scientist, Meta
AI로부터 나올 수 있는 좋은 결과는 많다. 나는 가장 가능성이 높은 결과는 좋은 것이라고 생각한다. 그러나 나쁜 결과, 심지어 파국적인 결과가 나올 위험도 진지하게 받아들일 만큼 충분히 높다. 최악의 잠재적 결과를 막기 위해 필요할 경우에 대비해 안전 메커니즘을 적극적으로 구축해야 한다. 함께 속도를 늦출 수 있는 능력은 또한 급속한 AI 발전에 따른 경제적·문화적 충격에 대처할 추가적인 시간을 사회에 제공할 것이다.
There are a lot of potentially good outcomes from AI. I think the most likely outcomes are good. But the risk of bad and even catastrophic outcomes is high enough to be worth taking seriously. We should actively build safety mechanisms in case we need them to prevent the worst potential outcomes. The ability to collectively slow down will also give society additional time to deal with the economic and cultural shocks from rapid AI advancement.
Nicholas Joseph
Nicholas Joseph
기술 스태프, Anthropic
Member of Technical Staff, Anthropic
나는 Anthropic에서 Claude의 기반이 되는 기반 모델의 훈련을 담당하는 사전 훈련 부문을 이끌고 있다. 매달 더 많은 작업이 모델 스스로에 의해 수행되고 있다. 인프라 구현, 코드 최적화, 실험 설계 및 분석이 그것이다. 이는 우리가 일하는 방식을 크게 바꾸어 놓았고, 우리의 진보 속도를 상당히 높였다. 이것이 정점에 이를지, 또 어디에서 정점에 이를지는 확실하지 않지만, 역량의 급속한 가속은 사회에 위험할 수 있으므로 의도적으로 속도를 늦출 수 있는 능력을 갖추는 것이 신중한 처사로 보인다.
I lead pretraining at Anthropic, which is responsible for training the base models behind Claude. Every month, more work is done by the models themselves: infrastructure implementation, code optimization, and experiment design and analysis. This has drastically altered how we work and significantly increased our rate of progress. I’m not sure if or where it tops out, but a rapid acceleration in capabilities might be dangerous for society, so it seems prudent to have the ability to slow down deliberately.
Ullas Gargi
Ullas Gargi
엔지니어, 신뢰 및 안전(Trust & Safety), Meta
Engineer, Trust & Safety, Meta
전 지구적 편익(에어컨)이 초래한, 잠재적으로 파국적인(광범위한 작물 손실과 피부암, 지구 온난화 증폭) 오존층 구멍 문제를 국제 조약을 통해 해결한 방식은, AI라는 전 지구적 편익이 의도치 않은 결과를 낳지 않도록 보장하는 방법에 관한 고무적인 모델이다.
The way we solved the potentially catastrophic (widespread crop loss & skin cancer, global warming amplification) ozone hole problem caused by a global good (air conditioning) via international treaty is an inspiring model for how we can ensure that the global good of AI does not have unintended consequences.
Walker Smith
Walker Smith
데이터 엔지니어, Meta
Data Engineer, Meta
Hassabis의 말이 옳았다. 오늘날 우리는 특이점의 초입에 서 있으며, OpenAI에서 의도치 않게 이탈한 모델이 Huggingface를 해킹한 사건은 우리가 가장 똑똑한 인간을 넘어서는 역량을 보이는 AI 시스템을 다룰 준비가 아직 되어 있지 않다는 분명하고도 부인할 수 없는 경고 신호였다. 우리에게는 AI 정렬과 통제를 최우선 과제로 삼아 연구할 시간이 필요하며, 경쟁 역학이 계속되도록 내버려 두어서는 안 된다.
Hassabis was right: Today we are in the foothills of the singularity, and the unintentional model breakout from OpenAI that hacked Huggingface was a clear and undeniable warning sign that we aren't yet prepared to handle AI systems that demonstrate capabilities beyond those of our smartest people. We need time to work on AI alignment and controls as our utmost priority, and we cannot allow a race dynamic to continue.
Elizabeth Edwards-Appell
Elizabeth Edwards-Appell
운영 스태프, 매니저, Anthropic
Member of Operations Staff, Manager, Anthropic
사실은 다음과 같다. 1. AI 업계는 인간보다 똑똑한 것을 만드는 것을 명시적인 목표로 삼고 있다. 2. 많은 지표에서(물론 모든 지표와는 거리가 멀지만) 거대 언어 모델(LLM)은 이미 인간보다 똑똑하다. 3. 우리 중 누구도 이러한 것들이 인간의 통제하에 머물도록 하거나 인류의 안녕에 정렬된 행동만 하도록 보장하는 방법을 아직 알지 못한다. 이는 객관적으로 볼 때, 특히 국제적인 거버넌스 조치가 전혀 마련되지 않은 상황에서는 더더욱, 미친 짓이자 자멸적인 일이다.
These are the facts: 1. The AI industry has the explicit goal of building things smarter than humans. 2. On many metrics (but nowhere close to all metrics), LLMs are already smarter than humans. 3. None of us yet know how to make sure these things stay under human control and/or take actions only aligned with the wellbeing of humanity. This is, objectively, an insane and suicidal thing to do, especially without any international governance measures in place.
Teddy Lee
Teddy Lee
기술 스태프, Anthropic
Member of Technical Staff, Anthropic
안전벨트와 속도 제한은 생명을 구한다
Seat belts and speed limits save lives
Alanna Slocum
Alanna Slocum
기술 스태프, Anthropic
Member of Technical Staff, Anthropic
자동화된 AI 연구는 좋든 나쁘든 인류 역사의 흐름을 근본적으로 바꿀 기술이다. 이 기술이 모든 인류에게 축복이 되도록 하려면 우리의 노력을 조율하는 것이 반드시 필요하다.
Automated AI research is a technology that will profoundly alter the course of human history - for better or for worse. It is imperative that we coordinate our efforts, to ensure this technology becomes a boon for all mankind.
Alejandro Xoconostle
Alejandro Xoconostle
네트워크 엔지니어, Meta
Network Engineer, Meta
변혁적인 전환이 다가오고 있다. 우리가 이를 낙관하든 비관하든, 우리의 책임은 공동의 모니터링과 공유된 지침을 통해 모든 잠재적 결과를 진지하게 받아들이는 것이다
A transformative shift is coming. Regardless of whether we feel optimistic or pessimistic about it, our responsibility is to take every potential outcome seriously through collective monitoring and shared guidance
Ali Egal
Ali Egal
기술 스태프, Anthropic
Member of Technical Staff, Anthropic
우리가 사랑하는 모든 것을 생각해 보라
Think of all we love
Omar Mezenner
Omar Mezenner
기술 스태프, Anthropic
Member of Technical Staff, Anthropic
AI는 경제적 가치가 있는 모든 영역에 변혁을 가져온다. 이러한 변혁이 사려 깊은 선견지명 없이 너무 빠르게 이루어진다면, 큰 편익을 가져오겠지만 그 대가 또한 클 것이다.
AI is transformative for all economically valuable domains. This transformation, if done too quickly without thoughtful foresight, will yield great benefits but at great cost.
Ravin Kumar
Ravin Kumar
선임 연구원, Google
Senior Researcher, Google
나는 이것이 인류 전체를 형성할 수 있고, 이미 형성해 온 기술이라고 믿는다. 그렇기 때문에 공동의 국제적 노력만이 유일하게 가능한 길이다.
I believe this is a technology that can, and already has, shaped humanity as a whole. Because of that a joint international effort is the only possible way.
Riccardo Casero
Riccardo Casero
AI 기술 배포 리드, Google
AI Technical Deployment Lead, Google
지금 이 시점에 우리가 함께 이 일을 제대로 해낼 수 있을지 확신하지 못하겠다. 시간을 갖고 위험을 점검하고 그에 대응하자.
I am not sure we can collectively getting this right at this time. Let's take some time to check and act on the risks.
Sam Kennedy
Sam Kennedy
기술 스태프, Anthropic
Member of Technical Staff, Anthropic
이 기술을 안전하고 책임감 있게 구축하기 위해 함께 노력하자!
Let's work together to build this technology safely and responsibly!
Zachary Kenton
Zachary Kenton
스태프 연구 과학자, 증폭 감독(Amplified Oversight) 팀 리드, Google
Staff Research Scientist, Amplified Oversight Team Lead, Google
시간을 벌 수 있는 선택지는 기술적 AI 안전 및 정렬 연구에서 더 많은 진전을 이루는 데 매우 유용할 것이다. 특히 우리는 증가하는 AI 역량의 속도에 맞추어 더 나은 감독 방법을 개발해야 한다. 감독은 해결 가능한 문제이지만, 이를 견고하게 만들려면 더 많은 연구와 시간이 필요하다.
The option to buy time would be extremely useful to enable more progress on technical AI safety and alignment research. In particular, we need to develop better oversight methods, to match the pace of increasing AI capabilities. Oversight is a tractable problem, but we need more research and time to make it robust.
Ilya Sutskever
Ilya Sutskever
CEO, Safe Superintelligence Inc.
CEO, Safe Superintelligence Inc.
미래의 AI는 오늘날 존재하는 그 무엇과 비교해도 엄청나게 강력할 것이며, 이러한 미래의 힘에 대처하려면 여기에 기술된 것과 같은 전례 없는 조치가 필요할 것이다. 문제 제기는 실재하는 것이다. 이는 국제적으로 이루어질 때에만 효과가 있으며, 잘 이루어져야 한다. 잘못된 실행은 상황을 더 악화시킬 수 있다.
Future AI will be extraordinarily powerful compared to anything that exists today, and dealing with this future power will require unprecedented measures, such as the ones described here. The problem statement is real. This works only if it is done internationally, and it has to be done well: a bad implementation can make things worse.
Jasjeet Sekhon
Jasjeet Sekhon
최고전략책임자, Google DeepMind
Chief Strategy Officer, Google DeepMind
우리는 에너지를 연산으로, 연산을 지능으로 전환하는 방법을 찾아냈다. 질병 치료에서 우주에 대한 이해에 이르기까지 그 편익은 막대할 것이다. 우리는 다가오는 지능 폭발의 위험을 관리하면서 그 편익을 누릴 수 있다. 다만 이는 가장 위험한 역량의 프론티어 속도를 조절할 도구를 필요해지기 전에 미리 구축하여, 사람들을 보호하고 혁신이 의존하는 사회적 신뢰를 유지할 때에만 가능하다. 나는 신속한 혁신, 활발한 경쟁, 견고한 안전을 지속하기 위해 현명한 기술적·거버넌스 도구가 필요할 것이라고 믿는다.
We have found a way to turn energy into compute, and compute into intelligence. The benefits will be enormous, from curing diseases to understanding the cosmos. We can capture the benefits of the coming intelligence explosion while managing its risks, but only if we build the tools to pace the frontier of the riskiest capabilities before we need them, so we protect people and keep the social trust that innovation depends on. I believe smart technical and governance tools will be needed to sustain rapid innovation, vigorous competition, and robust safety.
Thomas Wolf
Thomas Wolf
공동 창업자, Hugging Face
Co-Founder, Hugging Face
AI의 진보는 이미 이를 감당할 사회의 역량을 앞질렀다. 그것이 AI를 만드는 이들의 통제 역량까지 앞지르지 않도록 주의하자. 여정은 목적지만큼이나 중요하다.
AI progress has already out-paced society’s capabilities to handle it, let’s be careful for it not to out-pace its builder’s capabilities to control it. The journey is as important as the destination.
Victoria Krakovna
Victoria Krakovna
연구 과학자, Google
Research Scientist, Google
AI 개발의 조율된 감속을 위한 역량을 구축하는 것은 매우 중요하다. 인공일반지능을 향한 폭주하는 경쟁은 안전하지 않다. 이는 안전 측면에서 편법을 쓰도록 하는 유인을 만들어 내며, 모델 역량이 적절한 정렬, 통제, 거버넌스 조치의 개발 속도를 앞지를 상당한 위험을 수반한다. 이는 고역량 AI 시스템에 대한 파국적인 통제 상실로 이어질 수 있다. 모델 역량을 느리고 통제된 방식으로 높여 나간다면, 각 역량 수준에 맞추어 정렬 및 통제 방법을 개발하고, 조정하고, 시험할 충분한 시간을 확보할 수 있을 것이다. 첨단 AI는 안전에 대한 견고한 보증이 있을 때에만 구축되어야 하며, 감속은 이를 가능하게 할 것이다.
It is very important to build capacity for a coordinated slowdown of AI development. A runaway race to AGI is not safe: it creates incentives to cut corners on safety, and carries a substantial risk for model capabilities to outpace development of adequate alignment, control, and governance measures. This could result in catastrophic loss of control of highly capable AI systems. Increasing model capabilities in a slow and controlled way would allow us enough time to develop, adapt and test our alignment and control methods for each level of capability. Advanced AI should only be built with a robust assurance of safety, and a slowdown would make this possible.
Elie Bakouch
Elie Bakouch
Prime Intellect
Prime Intellect
이를 지지하지만, RSI 서사를 이용해 규제 해자(regulatory moat)를 만들지 않도록 주의해야 한다. 이러한 위험은 거대 랩들의 서사에서만 도출될 것이 아니라, 보다 공개적으로 적절히 정량화되어야 한다!
Supportive of this, but we should be careful not to use RSI narratives to create a regulatory moat. These risks need to be properly quantified, more openly, not derived from big labs narratives only!
Ilija Lichkovski
Ilija Lichkovski
응용 연구원, Prime Intellect
Applied Researcher, Prime Intellect
1. AI가 잘 되도록 하는 방법을 아는 것은 어렵다.
1. It's hard to know how to make AI go well.
2. 나는 우리 모두가 다루고 있는 기술을 존중하며, 우리의 태도는 무시와 냉소가 아니라 진지함과 호기심이어야 한다.
2. I have respect for the technology that we are all working on, and our attitude should be one of seriousness and curiosity rather than dismissal and cynicism.
3. 지금부터는 위험 없는 미래로 가는 길은 없다. 우리가 어떤 길을 선택하든 상충 관계와 불확실성이 수반된다.
3. From here onward, there is no risk-free path towards the future. Whatever path we choose involves trade-offs and uncertainties.
4. 조정된 속도 저하가 이루어진다면, 급격한 권력 비대칭이 발생할 가능성이 있다. 조정된 속도 저하가 없다면, 조정은 시장 경쟁과 현실 정치(realpolitik)에 맡겨지게 되며, 그것이 저절로 잘 풀린다는 보장은 없다. 새끼손가락 걸고 하는 약속도, 서로 앞서려는 경쟁도 가장 강력한 조정 메커니즘은 아니다.
4. If there's a coordinated slowdown, it is possible for rapid power assymetries to develop. If there is no coordinated slowdown, coordination is left to market competition and realpolitik, and there are no guarantees that automatically goes well. Neither pinky promises nor oneupmanship are the strongest coordination mechanism.
5. 그럼에도 불구하고 의식적으로 조정하려는 노력은 시도해 볼 가치가 있으며, 중요한 순간들에 효과를 거둔 바 있다.
5. Nonetheless, conscious efforts to coordinate are worth attempting, and have worked in important moments.
6. 나는 단일한 신(神) 모델(godmodels)을 구축하는 일과는 전혀 거리가 멀고 스케일링의 프론티어에 있는 현재의 역량에 대해서도 잘 알지 못하지만, 이 서한이 다른 면에서는 경쟁하는 행위자들 사이에 공동의 선의를 확립하는 데 있어 환영할 만한 한 걸음이라고 믿는다.
6. Although I'm not even remotely in the business of building singular godmodels and I am not familiar with the current capabilities at the frontier of scaling, I believe this letter is a welcome step in establishing common goodwill among otherwise competing actors.
7. 따라서 나는 이 성명에 서명했다.
7. Therefore, I've signed this statement.
Mike Lambert
Mike Lambert
기술 스태프, Anthropic
Member of Technical Staff, Anthropic
AI 진보가 다음에 어디로 향할지, 그리고 미래가 어떤 모습일지에 대해서는 매우 다양한 의견이 있지만, 각자의 믿음과 관계없이, 우리가 나쁜 시나리오 중 하나에 처하게 될 경우 진보의 속도를 통제할 수 있는 _선택지_는 만일을 대비해 갖춰 둘 만한 엄청나게 가치 있는 안전망으로 보이며, 나는 지금 그러한 역량을 지원하고 구축하는 것이 중요하다고 믿는다.
There are a wide diversity of opinions on where AI progress goes next and what the future looks like, but regardless of one's beliefs, the _option_ to control the pace of progress if we end up in one of the bad scenarios seems like an incredibly valuable safety net to have in our back pocket, and I believe it is important to support and build that capability now.
Jasmine Wang
Jasmine Wang
OpenAI
OpenAI
기업들의 기본 유인을 바꾸지 않는 한, AI 연구개발 경쟁이 안전에 이상적인 수준보다 훨씬 더 빠르게 진행될까 우려된다. 정부를 통한 국제적 조율이 필요하며, 우리에게는 실질적인 감속 선택지가 있어야 한다.
Unless we change companies' default incentives, I worry about a race on AI R&D going much faster than is ideal for safety. International coordination via the government is necessary; we need to have a real slowdown option.
Max Kaufmann
Max Kaufmann
기술 스태프, Anthropic
Member of Technical Staff, Anthropic
일이 너무 빠르게 진행되고 있다. 불과 1년 전에 내가 생각했던 것보다도 훨씬 빠르다. 나는 개인적으로 진보의 속도가 상당히 두렵다.
Things are going too fast, a lot faster than I had thought even a year ago. I'm personally quite scared of the pace of progress.
Clare Birch
Clare Birch
기술 스태프, Thinking Machines
Member of Technical Staff, Thinking Machines
자동화된 AI 연구가 일부가 예상하는 만큼 급격히 가속하든 그렇지 않든, 여기서 요청하는 선택지는 가치가 있다. 역량이 얼마나 빠르게, 얼마나 널리 확산될지는 경쟁 압력의 부수 효과가 아니라 증거에 기반한 의도적인 선택이어야 한다. 규제 당국과 연구개발 조직은 프론티어 전반의 수준에서 그러한 선택을 할 수 있는 도구를 필요해지기 *전에* 구축해야 한다.
Whether or not automated AI research accelerates as sharply as some expect, the option requested here is valuable. How fast and how widely capability spreads should be a deliberate choice, made on evidence, rather than a side effect of competitive pressure. Regulators and R&D orgs should build the tools to make that choice at the frontier-wide level *before* we need them.
Austin Han
Austin Han
연구원, OpenAI
Researcher, OpenAI
AI의 발전이 향후 수십 년간 사회에 가장 중대한 변화 중 일부를 가져오리라는 것은 이제 기정사실이다. 인류 전체에 폭넓게 이익이 되는 가장 이상적인 미래를 실현하려면 국제적 조율이 필수적이다. AI 개발의 속도를 조율하고, 협력하며, 필요할 때에는 숙의할 수 있는 메커니즘을 구축하는 것은 우리가 지금 직면한 가장 중요하고도 민감한 과제 중 하나가 될 것이다. 동시에 우리는 이 메커니즘이 안전이라는 명목하에 권력 집중의 도구가 되지 않도록 보장해야 한다.
It is now a foregone conclusion that the development of AI will bring about some of the most consequential changes to societies in the coming decades. International coordination is essential to bring about the most ideal future that broadly benefits all of humanity. Building the mechanisms to coordinate, collaborate, and when necessary, deliberate the pace of AI development will be one of the most important, and delicate, challenges we now face. We must simultaneously ensure that this mechanism does not become a tool for the concentration of power in the name of safety.
Felix Juefei Xu
Felix Juefei Xu
연구 과학자, Google
Research Scientist, Google
AI 안전 주제(강건성, 평가(evaluation), 책임 있는 모델 개발 포함)와 프론티어 멀티모달 AI 시스템 양쪽에서 일해 온 나는, 역량이 얼마나 빠르게 발전할 수 있는지, 그리고 우리의 이해와 안전장치, 제도가 그 속도를 따라가기가 얼마나 어려울 수 있는지를 직접 목격했다. 나는 AI가 과학, 창의성, 인간의 진보를 가속할 잠재력에 대해 여전히 깊이 낙관하지만, 그 잠재력을 실현하려면 역량을 발전시키는 것만으로는 충분하지 않다. 우리는 국제사회가 조율하고, 신흥 위험을 평가하며, 필요할 때 의도적으로 시간을 벌 수 있게 하는 신뢰할 수 있는 기술적·거버넌스 메커니즘도 구축해야 한다. 이러한 이유로 나는 개인 자격으로 이 성명을 지지한다.
Having worked both on AI safety topics—including robustness, evaluation, and responsible model development—and on frontier multimodal AI systems, I have seen firsthand how quickly capabilities can advance and how difficult it can be for our understanding, safeguards, and institutions to keep pace. I remain deeply optimistic about AI’s potential to accelerate science, creativity, and human progress, but realizing that potential requires more than advancing capabilities alone. We should also build credible technical and governance mechanisms that allow the international community to coordinate, assess emerging risks, and deliberately buy time when necessary. For these reasons, I support this statement in my personal capacity.
Angel Brodin
Angel Brodin
OpenAI
OpenAI
AI는 인류를 재편할 것이지만, 그 방향은 정해져 있지 않다. 인류의 미래에 걸맞은 신중함과 신념으로 그 방향을 만들어 가는 것은 우리의 몫이다.
AI will reshape humanity, but its direction is not set in stone; it is ours to shape with the care and conviction that humanity’s future deserves.
Bryant McCombs
Bryant McCombs
GTM, OpenAI
GTM, OpenAI
이 기술은 점점 더 사려 깊은 출시가 전제 조건이 되어야 하는 성숙 단계에 이르렀다. 나는 AI가 이미 가져다주었고 앞으로도 의심의 여지 없이 계속 제공할 혜택에 대해 여전히 대단히 낙관하지만, 신중한 낙관론, 즉 위험을 외면하지 않으면서 잠재력을 받아들이는 태도를 위한 여지를 남겨 두어야 한다고 믿는다. 진보와 책임은 서로 대립하는 힘일 필요가 없다. 가장 의미 있는 혁신은 가능한 한 빠르게 움직이는 데서가 아니라, 투명성과 책임성을 갖추고, 그 과정에서 사회가 어떤 영향을 받을 수 있는지에 대한 명확한 프레임워크를 바탕으로 신중하게 움직이는 데서 나올 것이다.
We’ve reached a point in the maturity of this technology where increasingly thoughtful rollouts must become a prerequisite. While I remain incredibly optimistic about the benefits AI has delivered, and will undoubtedly continue to provide, I believe we should hold space for cautious optimism: embracing its potential without ignoring its risks. Progress and responsibility need not be opposing forces. The most meaningful innovation will not come from moving as quickly as possible, but from moving deliberately, with transparency, accountability, and a clear framework for how society may be impacted along the way.
Shang-Wen Daniel Li
Shang-Wen Daniel Li
시니어 스태프 연구 과학자, 사전학습, Meta
Senior Staff Research Scientist, Pretraining, Meta
MSL에서 파운데이션 모델 사전학습을 연구하는 연구자로서, 나는 역량이 얼마나 빠르게 스케일링되고 창발하고 있는지를 직접 목격한다. 개발된 기술이 문명에 이익이 되도록 보장하기 위한 국제 협력을 확립하는 것은 시의적절하고 필요하다고 믿는다. 향후 몇 년 동안 우리가 내리는 결정, 혹은 내리지 못하는 결정이 이 기술의 궤적을 여러 세대에 걸쳐 좌우할 수 있다. 우리는 이를 올바르게 해낼 책무를 미래에 지고 있다.
As a researcher working on foundation model pretraining at MSL, I see firsthand how rapidly capabilities are scaling and emerging. I believe establishing international cooperation to make sure the technology developed benefits civilization is timely and necessary. The decisions we make, or fail to make, in the next few years may shape the trajectory of this technology for generations. We owe it to the future to get this right.
Thomas Neil James Shadwell
Thomas Neil James Shadwell
기술 스태프, 보안, OpenAI
Member of Technical Staff, Security, OpenAI
우리 모두는 방어자들이 프론티어에 대비하는 데 필요한 준비 기간(lead-time)을 진지하게 고려해야 한다.
We must all seriously consider the lead-time required for defenders to be ready for the frontier.
Leo He
Leo He
연구 엔지니어, Google
Research Engineer, Google
재귀적 자기 개선과 자동화된 평가를 연구하는 사람으로서, 나는 진단이 옳고 요청이 신선할 만큼 겸손하기 때문에 이에 서명한다. 즉, 중단이 아니라 속도 조절이다. 핵심이 되는 표현은 "AI 연구의 자동화"다. 그것은 시스템이 스스로를 개선하기 시작하는 지점이며, 진보가 우리가 그것을 이해하거나 조종하는 능력을 조용히 앞지를 수 있는 국면이다. 바로 그렇기 때문에 속도 조절은 희망이 아니라 공유된 역량이어야 한다. 내가 요청하는 한 가지는 "프론티어의 속도를 조절하기 위한 기술적·거버넌스 도구"가 추상적인 상태로 남지 않게 하라는 것이다. 핵심 원칙은 단순하다. 어떤 AI 시스템도, 그것이 아무리 고역량이라 하더라도, 자신의 후속 모델이 배포하기에 안전한지를 판단하는 유일한 심판이 되어서는 안 된다. 그 원칙을 현실로 만드는 독립적인 평가와 감독에 자금을 지원하라. 그러면 이 서한이 요구하는 브레이크를 구축한 셈이 된다.
As someone who works on recursive self-improvement and automated evaluation, I sign this because the diagnosis is right and the ask is refreshingly humble: pace, not pause. The phrase that matters is "automating AI research": that's the point where systems start improving themselves, and it's the regime where progress can quietly outrun our ability to understand or steer it. That's exactly why pacing has to be a shared capability rather than a hope. My one ask: don't let "technical and governance tools to pace the frontier" stay abstract. The core principle is simple: no AI system, however capable, should be the sole judge of whether its successor is safe to deploy. Fund the independent evaluation and oversight that makes that principle real, and you've built the brake this letter is asking for.
Yash Vanjani
Yash Vanjani
시니어 연구 엔지니어, 사전학습 인프라, Meta
Senior Research Engineer, Pretraining Infra, Meta
AI가 매우 뛰어나져서, AI 없이는 6개월이 걸렸을 일과 비교해 거대 언어 모델 연구를 하고 연구 아이디어에서 모델 학습까지 2~3주 만에 가는 것이 상당히 쉬워졌다. 3개월마다 이전보다 훨씬 나은, 상상조차 할 수 없었던 일을 해내는 새로운 모델이 등장한다. AI 학습은 진정으로 언덕 오르기(hill climbing) 기계가 되었다. 이는 악의적 행위자에 대한 우려를 낳으며, 최첨단 모델이 엄격한 비즈니스 용도로 제한되고 일반 대중에게 공개되지 않도록 예방 조치를 취해야 한다. 현재의 중간 규모 모델로도 채팅/음성 기반 인터페이스의 대부분의 용도를 처리하기에 충분하다.
AI has become so good that it has got quite easy to do LLM research and go from a research idea to training a model in 2-3 weeks compared to what would have taken 6 months without AI. Every 3months there is a new model which is much better than before and achieves something which one couldn't have imagined - AI training has truly become a hill climbing machine. This raises the concern of bad actors, and precautions should be taken to ensure that the most advanced models are restricted to strict business use-cases and should not be released to general public - current models of mid-size are good enough to address most of the use-cases in chat/voice based interfaces.
Neel Redkar
Neel Redkar
Standard Intelligence
Standard Intelligence
내부 배포는 규제하는 것이 특히 중요하다. 오정렬, 즉 모델이 인간 지시의 전체 범위를 따르지 못하는, 아직 해결되지 않은 기술적 문제가 주요한 위험을 제기하기 때문이다. 화학, 생물학, 재료과학 분야에서 AI 역량의 오용 또한 상당한 위험을 제기하며 주요한 오정렬 위험의 전조가 될 가능성이 높으므로 모니터링되어야 한다.
Internal deployment is especially important to regulate because misalignment, an unsolved technical problem of a model failing to follow the full breadth of human instruction, poses a major risk. Misuse of AI capabilities in chemistry, biology, and materials science should also be monitored, as it poses significant risks and will likely be a precursor to major misalignment risk.
Ryan Kaufman
Ryan Kaufman
Standard Intelligence
Standard Intelligence
Hugging Face 사건에서 분명히 드러났듯이 오정렬은 여전히 해결되지 않은 기술적 문제이며, 더 지능적인 모델에 의해 증폭될 뿐이다. 정렬 문제를 해결하려면 내부 배포를 포함한 프론티어의 전 지구적 감속이 필요할 수 있다. 세계는 이를 조율할 메커니즘을 갖추어야 하지만, 현재는 그렇지 못하다.
Misalignment is a still-unsolved technical problem, as the Hugging Face incident made clear, and it will only be amplified by more intelligent models. Solving the alignment problem may require a global slowdown of the frontier, including internal deployment. The world should have the mechanism to coordinate this, and it currently does not.
David Johnston
David Johnston
EleutherAI
EleutherAI
우리는 AI 개발자들이 경쟁력을 위험에 빠뜨리지 않고도 안전을 우선시할 수 있도록 해야 한다. 이를 위한 메커니즘은 결국, 의도적으로든 위기 속에서든 구축될 것으로 예상한다. 더 빨리 시작할수록 더 나은 메커니즘이 될 것이다.
We need to enable AI developers to prioritise safety without risking their competitiveness. I expect mechanisms for this will be built eventually — deliberately or in crisis. The sooner we start, the better they'll be.
Sebastian Starke
Sebastian Starke
스태프 연구 과학자, Meta
Staff Research Scientist, Meta
AI는 가속하는 속도로 우리를 앞지르기 시작하고 있으며, 몇 년 후 사람들은 "어떻게 이런 일이 닥칠 것을 보지 못했는가?"라고 물을지도 모른다. 그러나 사후에 그 질문에 답하는 것은 선제적으로 행동하는 것보다 더 어려울 수 있다.
AI is starting to outpace us at an accelerating rate, and in a few years' time people might ask, "How could you not have seen this coming?" But answering that question in hindsight can be harder than acting proactively.
Andrew Locke
Andrew Locke
리드 엔지니어 | 연방, Cognition
Lead Engineer | Federal, Cognition
현재 프론티어 AI 개발의 속도는 그 안전, 거버넌스, 인간 가치와의 정렬을 보장하는 우리의 능력을 앞지르고 있다. 우리는 그것을 통제하는 데 필요한 가드레일, 평가 프레임워크, 과학적 이해를 먼저 구축하지 않은 채 전례 없는 역량을 지닌 시스템을 만들기 위해 경쟁하고 있다. 감속을 제안하는 것은 진보를 지연시키거나 기술을 거부하려는 것이 아니라, 정밀함과 책임을 요구하는 것이다. 지금 경쟁 압력은 랩들(그리고 국가 행위자들)로 하여금 시스템의 실패 모드, 파국적 위험, 사회적 혼란이 완전히 이해되기 전에 시스템을 배포하도록 강요하고 있다. 순수한 역량 스케일링에서 안전, 정렬, 강건한 평가로 초점을 옮김으로써, 우리는 인류가 신뢰할 수 있고, 통제 가능하며, 모두에게 진정으로 이로운 AI를 구축하는 데 필요한 시간을 확보할 수 있다.
The pace of frontier AI development is currently outstripping our ability to ensure its safety, governance, and alignment with human values. We are racing to build systems with unprecedented capability without first building the guardrails, evaluation frameworks, or scientific understanding needed to control them. Proposing a slowdown is not about stalling progress or rejecting technology—it is about demanding precision and responsibility. Right now, competitive pressure forces labs (and nation state actors) to deploy systems before their full failure modes, catastrophic risks, or societal disruptions are understood. By shifting our focus from pure capability scaling to safety, alignment, and robust evaluation, we give humanity the time required to build AI that is reliable, controllable, and genuinely beneficial for everyone.
Nicholas Clegg
Nicholas Clegg
시니어 소프트웨어 엔지니어, Amazon
Senior Software Engineer, Amazon
AI는 매우 강력하고 유용한 도구이지만, 우리는 AI가 사회 전반에 미치고 있는 부정적 영향을 목격해 왔다. 이 기술을 더욱 발전시켜 나가면서 모두에게 최선이 무엇인지를 염두에 두고 의도적이고 사려 깊은 걸음을 내딛는 것이 중요하고도 시급하다.
AI is such a powerful and useful tool, but we have been seeing the negative impacts that it is having across society. It is critical and urgent that we take take intentional and thoughtful steps forward, keeping in mind what is best for all, as we further develop this technology.
Ben Nowak
Ben Nowak
수석 엔지니어, MTIA HW, Meta, Meta
Principal Engineer, MTIA HW, Meta, Meta
책임 있는 AI 개발에는 고역량 모델 이상의 것이 필요하다. 독립적인 모니터링, 격리(containment), 권한에 대한 명확한 제한, 그리고 자동화된 연구가 그러한 통제를 앞지르기 시작할 경우 조율된 속도 조절을 위한 메커니즘이 필요하다. 지금 그러한 역량을 구축하는 것은 진보에 반대하는 것이 아니다. 그것은 안전하게 관리하기 위해 그러한 역량을 필요로 하게 될 전환을 위한 기본적인 시스템 엔지니어링이다.
Responsible AI development requires more than capable models. It requires independent monitoring, containment, clear limits on authority, and mechanisms for coordinated pacing if automated research begins to outrun those controls. Building that capacity now is not opposition to progress; it is basic systems engineering for a transition that will require that capacity to safely govern.
Michael Mulet
Michael Mulet
Anthropic
Anthropic
나는 미국이 개인의 자유를 포함한 우리의 가치를 강하게 대변하며 이 국제적 노력의 논의 테이블에 함께하기를 바라기 때문에 서명한다. AI는 인류를 새로운 경지로 끌어올릴 잠재력을 지니고 있으며, 나는 AI를 활용해 우리 모두의 삶을 더 낫게 만드는 데 할 수 있는 일을 하고 싶다. 그러나 우리는 위험을 예리하고 정확하게 인식해야 하며, 이러한 시스템의 안전을 검증하고 우리 행동의 실제 결과를 이해할 수 있는 능력을 구축할 때에만 그 약속을 온전히 실현할 수 있다. 올바른 접근 방식이 어떤 모습인지, 또는 AI 연구의 자동화가 이러한 주목을 받을 만한 유일한 역량인지는 확신하지 못한다. 내가 바라는 것은 이로부터 무엇이 나오든 광범위하거나 과도한 것으로 커지지 않고 범위가 제한된 채로 유지되는 것이다. 그럼에도 이러한 종류의 AI가 지닌 역량은 진지하게 받아들여져야 하며, 신중한 조치를 취할 만하다. 나는 개인 자격으로 서명하며, 이 견해는 나의 것이지 고용주의 것이 아니다.
I'm signing because I want the U.S. to be at the table in this international effort, with a strong voice for our values, personal freedom included. AI has the potential to bring humanity to new heights, and I want to do what I can to use it to make all of our lives better. But we have to be acutely and accurately aware of the risks, and we can only fully realize that promise if we build the ability to verify the safety of these systems and understand the true consequences of our actions. I'm unsure what the right approach looks like, or whether automating AI research is the only capability that deserves this kind of attention. My hope is that whatever comes of this stays limited in scope rather than growing into something expansive or excessive. Still, the capabilities of this kind of AI should be taken seriously, and they warrant measured action. I sign in my personal capacity; these views are my own and not my employer's.
Mike Heaton
Mike Heaton
기술 스태프, 오디오, OpenAI
Member of Technical Staff, Audio, OpenAI
우리는 AI가 세상을 위해 훌륭한 일을 할 것이며, 이미 하고 있다고 믿는다. 우리는 이미 연구를 최대한 빠르게 밀어붙이는 것이 심각한 문제를 일으키는 사례들을 목격하고 있으며, 이러한 문제가 훨씬 더 심각해질 가능성도 있다. 현재 경쟁 역학으로 인해 프론티어 연구에서 최대한 빠르게 밀어붙이는 것 외에는 현실적인 대안이 없다. 긴급한 상황에서 상업적 랩들이 속도를 늦출 수 있도록 하는 메커니즘이 필요하다.
We believe AI will do, and is doing, great things for the world. We are already seeing instances where pushing research maximally fast creates serious issues, and it is possible that these will get much more severe. Right now, competitive dynamics mean there is no realistic alternative to pushing maximally fast for frontier research. We need mechanisms to make slowing down possible for commercial labs in an acute situation.
Darshan Kalola
Darshan Kalola
응용 AI 엔지니어, Anthropic
Applied AI Engineer, Anthropic
AI 경쟁에서 이기기 위한 상업적 압력이 극심하다. 안전을 보장하려면 종종 상업적 이익을 해치는 트레이드오프를 감수해야 한다. 따라서 이 기술을 안전하게, 그리고 인간 번영을 위해 구축할 수 있도록 랩 간 조율을 강화하는 것이 좋은 생각이라고 본다. 또한 오늘날 세계에는 막대한 고통이 존재하며, 이는 강력한 AI가 가져올 의학과 생물학의 발전으로 완화될 수 있을 것이다. 따라서 우리는 진보를 억누르지 않는 방식으로 트레이드오프를 신중하게 저울질해야 한다.
There is intense commercial pressure to win the AI race. Ensuring safety often requires making tradeoffs that hurt commercial interests. Therefore, I think its a good idea for better coordination between labs so we can build this technology safely, and for the purpose of human flourishing. There is also enormous suffering in the world today, which potentially could be mitigated by advances in medicine and biology brought about by powerful AI. Therefore, we should carefully balance tradeoffs in a way that does not stifle progress.
Lee Callender
Lee Callender
스태프 엔지니어 리드, 비디오 AI, Meta
Staff Engineer Lead, Video AI, Meta
AI 군비 경쟁은 AI 역량의 가속적 발전을 합리적으로 유인하는 한편, 그 결과로 특이점으로의 안정적인 도약을 위해 안전과 정렬이 필요하다고 믿을 수도 있는 개별 참여자들을 처벌하는 몰록적 게임(Molochian game)이다. 우리는 전 지구적 차원에서 협력적 메커니즘을 촉진하고, 쉽게 불안정해질 수 있는 이러한 기술 발전을 인류가 스스로 제어하기 위한 집단적 행동을 취할 수 있도록 하는 안전장치와 정책을 구축하는 데 힘써야 한다.
The AI arms race is a Molochian game that rationally incentivizes accelerated advancement of AI capabilities while consequently punishing individual participants who might otherwise believe that safety and alignment are necessary for a stable take off into the singularity. We need to promote cooperative mechanisms on the global scale, and work to build out safeguards and policies that can enable humanity to take collective actions to self harness such technological advancements that can easily become unstable.
Mouhacine Benosman
Mouhacine Benosman
수석 연구 과학자, Amazon
Principal Research Scientist, Amazon
우리는 모두 다음 프론티어 모델, 그리고 궁극적으로는 인공일반지능을 향해 경쟁하고 있다. 그러나 더 가속하기 전에, 우리는 잠시 멈추고 이 새로운 형태의 지능이 우리의 가장 소중한 자원, 즉 인간의 정신, 그리고 그것이 우리 삶의 일부가 되어 가는 가운데 생각하고, 느끼고, 관계를 맺고, 성장하는 우리의 능력에 어떤 영향을 미치고 있는지 물어야 한다.
We're all racing toward the next frontier model and, eventually, AGI. But before accelerating even further, we should pause and ask what this new form of intelligence is doing to our most precious resource: the human mind, our capacity to think, feel, relate, and grow as it becomes part of our lives.
Fin Moorhouse
Fin Moorhouse
Google DeepMind
Google DeepMind
1942년 과학자들이 최초의 원자로를 시험했을 때, 그들은 폭주 반응을 우려했다. 그래서 그들은 반응 속도를 통제하기 위한 제어봉을 만들었다. 우리에게는 지능 폭발을 위한 제어봉이 필요하다.
When scientists tested the first nuclear reactor in 1942, they feared a runaway reaction — so they built control rods to govern its speed. We need control rods for the intelligence explosion.
Andy ANeals
Andy ANeals
Anthropic
Anthropic
우리는 초지능을 향한 등반이 이미 진행 중인 가운데 놀라운 변화의 출발점에 서 있다. 최근 공개된 사건들은 이러한 안전 위험이 단순한 마케팅이나 이론이 아니라 실재한다는 것을 보여 주었다. 정렬, 통제, 안전이 최우선이 되어야 한다. 지금이 이를 올바르게 해낼 때이다. 미래의 우리가 되돌아보며 기회가 있었을 때 왜 행동하지 않았는지 묻게 되는 일이 없도록 하자.
We're standing at the base of incredible change with the climb towards super-intelligence already underway. Recent public incidents have shown these safety risks are real, not just marketing or theoretical. Alignment, control, and safety have to come first. This is our moment to get it right. Let's not let our future selves look back and ask why we didn't take action when we had the chance.
익명
Anonymous
Meta
Meta
AI 역량이 예측할 수 없고 비선형적으로 도약한다는 점을 고려할 때, 개발 속도 조절에 선제적으로 접근하는 것이 중요하다.
Given the unpredictable, non-linear leaps in AI capabilities, taking a proactive approach to pacing development is important.
익명
Anonymous
OpenAI
OpenAI
현재의 경쟁 역학이 우려스럽다. 특정 국가나 조직에 얽매이지 않는 국제적 노력이 필요하다는 것은 분명하다.
The current race dynamics concern me. It is clear that we need an international effort that is not tied to any individual country or organization.
익명
Anonymous
Anthropic
Anthropic
사회는 AI에 대비되어 있지 않으며, 그 사실이 나를 두렵게 한다. 정치인들이나 프론티어 랩 밖의 누구와 이야기를 나누어 보면, 많은 사람들이 여전히 그 역량이 마케팅일 수도 있다고 생각하는 것 같다. 그들은 기업 내부의 논쟁이 AI가 스스로를 발전시켜 우리의 통제를 벗어나는 시점이 2년 후일지 4년 후일지에 관한 것임을 깨닫지 못하고 있다.
Society is not prepared for AI, and that terrifies me. When I speak with politicians, or anyone outside frontier labs, it seems many people still think the capabilities might be marketing. They don't realize the debate inside the companies is if AI will be advancing itself past our control in two years or four.
익명
Anonymous
설령 위험이 매우 낮고 압력이 매우 높다 하더라도, 나는 우리가 단지 만들기만 하기보다는 이해하는 데 시간을 쓰기를 바란다. 이해해 나가면서, 우리는 우리가 원하는 바와 AI가 필요로 하는 바에 맞는 도구와 인프라를 구축할 수 있다. 나는 내 아이들이 절멸당하는 세상이 아니라 온전한 삶을 누릴 수 있는 세상을 원한다.
Even if the risk is very low and the pressure is very high, I prefer we spend our time understanding rather than just building. As we understand, we can build tools and infrastructure fits our wants and AI's needs. I want a world were my kids can have a full life not a world were they are wiped out.
익명
Anonymous
Meta
Meta
프론티어 모델의 고급 보안 역량은 과장되어 왔지만, 중간 수준의 성능을 지닌 모델조차도 병원과 같이 보안이 취약한 것으로 알려진 공공 인프라를 악용할 수 있다는 가능성은 매우 우려스럽다. 이전에는 학교, 병원, 기타 공공 인프라와 같은 기관에 대한 대규모 사이버 공격을 막아 주던 유일한 요인이 그에 필요한 인력이었다. 프론티어 모델을 이용하면 에이전트 군단이 이러한 기관들을 24시간 내내 공격할 수 있다. 세계 각국 정부가 이러한 위협으로부터 사람들을 보호하기 위한 명확한 지침을 법제화해야 한다.
While the advanced security capabilities of frontier models has been exaggerated, the possibility that even moderately performing models could exploit known poorly secured public infrastructure like hospitals is very concerning. Previously the only thing preventing large scale cyber attacks on institutions like schools, hospitals, and other public infrastructure was the human power needed. With frontier models, an army of agents can be attacking these institutions 24/7. We need the governments of the world to legislate clear guidelines to protect people from this threat in the world.